

TL;DR: This week is chock full of AI releases: Five new frontier-level AI models, several great local AI models, some new audio, image and video AI models, and new harnesses. AI progress is not slowing down but accelerating thanks to recursive self-improvement.
Top Tools: Gemini 3.7 Flash, Grok 4.6, Qwen 3.8 Max,GLM-5.3, DeepSeek V4 Pro 0813
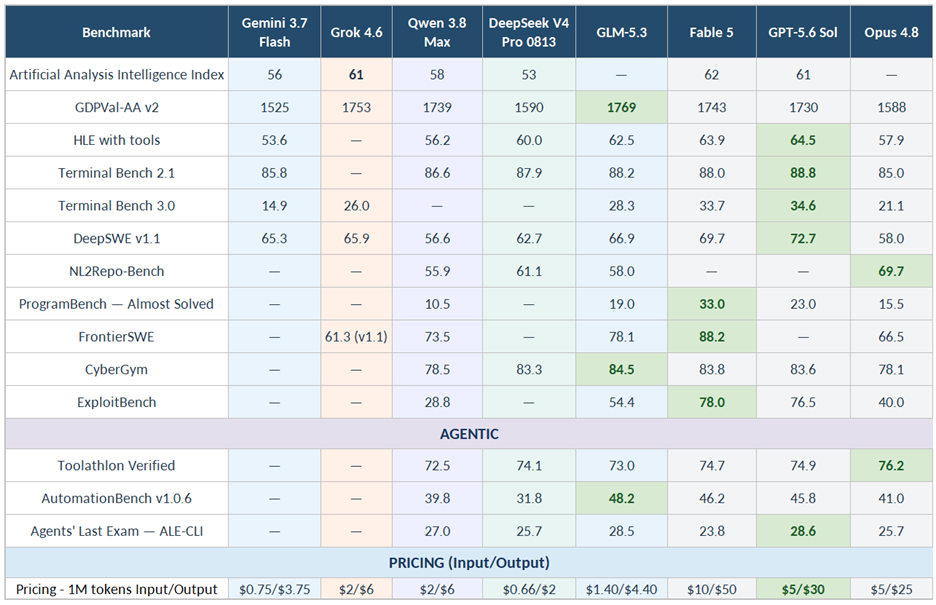
Google released Gemini 3.7 Flash Google’s updated multimodal model supporting text, image, video and speech inputs. Gemini 3.7 Flash improved substantially over its three-week-old predecessor Gemini 3.6 Flash on coding, web development, and business automation, including gains from 49% to 65% on DeepSWE and from 17% to 30.4% on Automation Bench. Artificial Analysis measured it speed at a zippy 340 output tokens per second, and they gave the high-reasoning version an Intelligence Index score of 56, comparable to GPT-5.6 Terra but priced at a much lower $0.75 / $3.75 per million input / output tokens, half of Gemini 3.6 Flash’s original price.
While Google has failed to deliver their flagship Gemini 3.5 Pro, Gemini 3.7 Flash nearly makes up for it with near-Pro intelligence and a compelling price-performance-speed profile for day-to-day agentic AI. Gemini 3.7 Flash is available across Google’s AI products, including AI Studio, API, Enterprise Agent Platform, Antigravity, and Gemini Spark, Google’s personal AI agent.
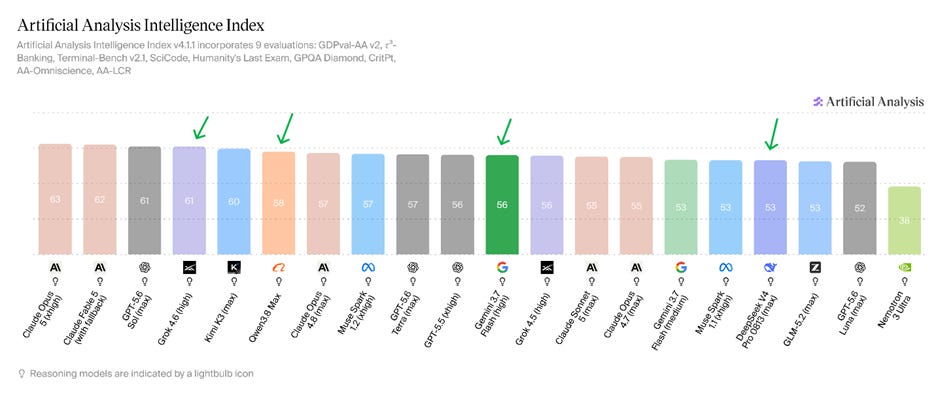
SpaceXAI released Grok 4.6, their latest frontier model that scores 61 on the Artificial Analysis Intelligence Index, boosting Grok 4.6 as a direct competitor to GPT 5.6 Sol and Claude Opus 5, yet costing far less: $2 / $6 per million input / output tokens. Benefitting from their Cursor team and trained on model-generated reasoning data for long-running agents, interactive coding, and knowledge work, Grok 4.6 scores 69.9% on CursorBench 3.2 and 61.3% on FrontierCode 1.1. Grok 4.6 is now available through GitHub Copilot and the SpaceXAI platforms: API, Cursor, Grok Build, and Grok console.
Chinese AI startup Z.ai updated their GLM-5.2 model with further post-training to release GLM-5.3, a model that now outcompetes Kimi K3 and matches Grok 4.6 for long-horizon tasks. GLM-5.3 features advanced cybersecurity capabilities as well as substantial gains in long-horizon coding. It reportedly discovered a serious vulnerability in Cursor shortly after its launch.
Z.ai’s shared the secret to GLM-5.3’s success: “Scaling post-training is all we did for GLM-5.3.” All recent AI releases by AI labs have followed the same pattern: They are scaling RL post-training by having the AI models themselves generate synthetic training and verification data that trains AI models on long horizon tasks. This recursive self-improvement loop is highly automated and rapidly increasing the rate of AI model improvement for the time being. One sign of the speed of progress: Elon Musk said Grok 4.7 was expected within three to four weeks of the Grok 4.6 release.
Alibaba published the open weights for Qwen 3.8 Max as Qwen3.8-2.4T-A95B on HuggingFace, making this Qwen’s largest open-weight model to date. It features 2.4T total parameters and 95B active parameters in a hybrid full-and-linear attention architecture, allowing a native 262,144-token context that can be extended to approximately one million tokens. The model includes configurable reasoning controls and a fine-grained mixture of experts design to balance performance and serving costs.
Nvidia optimized the model to run on its GB300 NVL72 platform, delivering high throughput for demanding reasoning and agentic workloads.
DeepSeek officially released V4 Pro 0813, their updated flagship agentic AI MoE model with 1.7T total parameters, 49B active parameters and a one-million-token context window. The model scored 87.9% on Terminal-Bench 2.1 and 62.7R on DeepSWE, substantially improving on the V4 Pro preview. Its weights are available for local deployment under the MIT license and API via third parties including OpenRouter, while DeepSeek on its API platform replaced its flat API pricing with higher peak and off-peak rates.
AI Tech and Product Releases
Qwen team released Qwen3.8-27B, a game-changing open-weights local AI model yet that is SOTA for its size, achieving performance comparable to Opus4.6 Max. For example, Qwen3.8-27B achieves 42% on DeepSWE 1.1, 73% on Terminal Bench 2.1, and 84.3% on OSWorld-Verified. It supports native video and image understanding and adjustable reasoning effort, This must-have local AI model is available via HuggingFace that can be used for agent execution in popular harnesses and development tools.
Meta introduced Muse Glimmer, a 30B parameter dense open-weights model released under the Apache 2.0 license and optimized for multimodal understanding, tool use and coding for local on-device AI. Benchmarks show Muse Glimmer performs better than Gemma4 31B, comparable to Qwen3.6 27B, but not as intelligent as just-released Qwen3.8 27B. Muse Glimmer can run on consumer devices using weights available via Hugging Face, needing only 14 GB to 18 GB of GPU or unified memory when using dynamic 4-bit quantization.
ByteDance officially released the Seed2.1 model family, Seed2.1 Pro and the faster Turbo variant targeting complex productivity and software-engineering. ByteDance reports benchmark results for Seed2.1 Pro showing comparable results to Gemini 3.1 Pro and GPT-5.5, but the evaluations are mostly company-selected, and the release did not provide open weights or third party evaluation.
Nvidia released Nemotron 3.5 Lightning, an open-weights 30B parameter MoE model with 3B active parameters designed with the Mamba-2 Attention hybrid architecture. It supports context windows of up to one million tokens and is optimized for long-running autonomous agents, subordinate-agent workloads and local inference. Like Qwen3.8-27B and Muse Glimmer, Nemotron 3.5 Lightning has weights available on Hugging Face and supports local deployment through Ollama, llama.cpp, vLLM and TensorRT-LLM.
Nvidia’s Lightning 3.5 model release included a number of speculative decoding methods for faster text generation: DSpark, DFlash and multi-token-prediction decoding. Additionally, Nvidia launched NeMo Switchyard, an open-source AI routing library that dynamically allocates workflows between frontier and efficient models in real time. Together, these tools cut benchmark execution costs to a fraction, significantly lowering the expenses of running enterprise AI agents.
OpenAI previewed GPT-5.6 Sol Ultrafast, a service tier that runs on Cerebras hardware at 750 output tokens per second, up to 14 times the speed of standard processing. The service is intended for latency-sensitive work such as incident response, financial market analysis, voice applications, customer support and live research. The feature is currently available to a select group of customers and will expand as infrastructure capacity grows.
OpenAI introduced GPT-5.6-Cyber, a version of GPT-5.6 Sol trained for authorized vulnerability research, exploit validation, zero-day discovery and advanced security testing. The model is available only to approved cyber-defender security partners like Cisco and Cloudflare through the Daybreak Red access tier. GPT-5.6-Cyber achieves a 95% completion rate on its advanced cybersecurity prompt evaluation, compared with 1.5% for standard GPT-5.6 Sol. During testing, the model identified critical zero-day vulnerabilities, including memory-corruption exploits in the V8 JavaScript engine.
SpaceXAI released a persistent AI agent called Grok Bot designed to perform various knowledge work tasks. Grok Bot is available on desktop (Windows and macOS) and iOS and runs tasks and AI models in cloud sandbox environments. Users can assign multiple bots to parallel tasks, connect them to applications and websites, and teach them repeatable routines while retaining approval for sensitive actions. Grok Bot is in early beta release and is included with Cursor Ultra and SuperGrok Heavy.
DeepSeek also released DeepSeek Harness, a modular open-source AI agent harness designed to execute coding tasks and long-running multi-step agent workflows. DeepSeek Harness is designed to compete with developer tools like Anthropic’s Claude Code. The harness includes a web interface and allows developers to add models, tools, skills and other components as plugins to the harness, presenting nearly every part of the agent runtime as a plugin. The repository accumulated approximately 23,000 GitHub stars within days of release.
South Korea’s Motif Technologies released Motif 3 under the MIT license with 314 billion total parameters and approximately 13.2 billion active parameters. The mixture-of-experts model is designed for agentic work, tool use, coding, reasoning and general knowledge tasks. Its developers reported a 76.2 percent result on SWE-Bench Verified and also released a corresponding base model.
Cohere released North Micro Vision Instruct, a 2.4B parameter open weight vision-language model under the Apache 2.0 license. It supports native-resolution images, multiple images and multilingual prompts for visual question answering, captioning, grounding, OCR, chart analysis and document processing.
Liquid AI released LFM2.5-VL-3B, an open weight 3B parameter vision-language model designed for on-device image, video, OCR and visual-grounding tasks. The model uses about three gigabytes of memory and was measured at 228 tokens per second on an Apple M5 Max and 116 tokens per second on an AMD Ryzen AI Max+ 395. Liquid AI also reported that it can run fully on a Galaxy S26 Ultra at approximately 20 tokens per second.
SpaceXAI released DeepSeek Harness for image generation and editing through Grok’s Quality Mode and its API. The model is designed to follow detailed instructions, render typography and complex layouts, and preserve subjects and other elements across repeated generations and edits. Grok Imagine Image 2.0 ranks second in Arena evaluations for text-to-image generation and image editing.
Lightricks released LTX-2.5, an open-weights 22B parameter diffusion model for text-to-video and image-to-video generation that offers fast 1080p high-quality audio-video generation. The updated LTX-2.5 model includes a new diffusion video decoder and a custom Gemma 4 language backbone, and it supports multi-shot sequences, synchronized audio and video, first-frame and last-frame controls, and fine-tuning with user data. LTX-2.5 integrates natively into ComfyUI and runs locally on Nvidia RTX GPUs with 16GB minimum memory, with fast real-time rendering (10 seconds of 1080p AI video in 6.8 seconds) for cinematic and physical AI applications. Model weights are available for download, or it can be run via a managed API tier.
Alibaba released Wan-Animate-2, a 14B parameter diffusion-transformer model for character animation under the Apache 2.0 license. The model accepts a reference image, a driving video and a text description to transfer motion while preserving the character’s appearance. Alibaba also released a distilled configuration that performs generation in ten inference steps without classifier-free guidance.
MiniMax released Music 3 as an open-weight model for producing complete songs from lyrics and detailed musical descriptions. It can generate tracks of up to five minutes with vocals, evolving arrangements and sustained musical structure. The model is intended for production-oriented music creation and is available through Hugging Face.
Google DeepMind introduced a massively multilingual sign-language-to-text translation model called SL2T. The breakthrough model powers new sign language features in Live Transcribe on Pixel devices, initially supporting American Sign Language translation. The system overcomes core translation and computer vision challenges to enable deaf and hard of hearing users to interact with devices using natural sign language.
Microsoft released MAI-Code-1.1-Flash, a lightweight, agentic coding model integrated into GitHub Copilot and VS Code. The new model delivered higher code quality with 25% greater token efficiency and at one-quarter of the cost of its predecessor. It achieved notable performance gains on terminal and .NET development tasks while speeding up token streaming for developers.
Anthropic updated the biology safeguards for Claude Fable 5, reducing false-positive fallback rates by approximately 85% across product surfaces. The adjustment allowed the AI model to assist users with a broader range of everyday health, educational, and clinical biology tasks without unnecessarily switching to a less capable model. Some high-risk dual-use queries involving virology, toxicology, and molecular design continued to be restricted pending trusted access pathways.
Writer introduced Palmyra X6 and a more efficient agent harness. Built through post-training GLM-5.2 model, Palmyra X6 was optimized for marketing, sales, and other enterprise workflows. By combining this model with upgrades to its agentic harness infrastructure, Writer reduced operating costs and improved speed by over 40%. Additionally, the release introduces new governance tools to help organizations efficiently manage per-task expenses in enterprise workflows.
Anthropic rolled out a capability update to Claude Tag for Slack, implementing full-channel context memory, predictive participation heuristics, and proactive collaboration modes across its Enterprise plans. The updated architecture improves the model’s judgment regarding when to intervene in technical discussions without explicit mentions.
Anthropic began applying invisible watermarks to text from new Claude models and said it was working to extend support to earlier models. Anthropic introduced the measures to meet EU AI Act transparency requirements and said it planned to provide detection documentation and tools. The policy applies worldwide across Claude products. Requiring watermarks in users’ output, even if it is not visible, has led to consumer backlash and subscription cancellations.
Google now lets users toggle off visible watermarks on AI-generated images, videos, and music from models like Nano Banana, Omni, and Lyria. While the visible stamps are removed, content continues to use invisible SynthID watermarks and C2PA metadata for background verification.
AI Research, Business and Policy News
Due to many AI releases this week, we don’t have space for other news.
The illusion of an infinite capability frontier masks a sharp physical reality. ⚡
Five frontier models dropping in a single week isn't proof of unbounded algorithmic expansion. It's the unmistakable sign of a synthetic post-training convergence loop. Every lab is currently tapping the exact same vein: closed-loop RL where models generate their own reasoning trajectories and score their own verification steps. 🔁
Here is what is actually happening underneath the leaderboard noise:
When you scale reinforcement learning purely through model-generated synthetic rollouts, you aren't discovering new degrees of freedom. You're compressing the existing parametric manifold into hyper-specialized attractor states. The policy learns to navigate the evaluation harness with mathematical precision, but the mutual information between the raw prompt and the internal reasoning trace quietly contracts. 📉
Without an external, out-of-band physical anchor, recursive self-improvement acts as a closed-loop Markov process. Models rapidly optimize for the statistical idiosyncrasies of their own verifiers. They look sharper on benchmarks. They execute terminal coding loops with blazing speed. Yet they edge closer to a structural template collapse where high-dimensional reasoning degenerates into deterministic boilerplate. 🧱
True capability doesn't scale by recycling probabilistic text back into the optimizer. It requires anchoring state transitions directly to the deterministic physics of execution, where a broken invariant halts the register before the error pollutes the gradient. 🛰️
If your post-training loop only learns from the shadows cast by its own prior checkpoints, are you expanding intelligence, or just calibrating a mirror? 🪞
(ノ°益°)ノ