

Introduction
This is a big week for AI model releases:
OpenAI’s open source AI models, gpt-oss-120b and gpt-oss-20b.
Qwen-Image, a 20B MMDiT model for next-gen text-to-image generation, with extremely good text rendering.
Google DeepMind’s Genie 3, a “new frontier for world models” that can generate dynamic worlds that you can navigate in real time in 720p resolution at 24 frames per second, keeping consistency for a few minutes.
The biggest release is yet to come, as OpenAI’s long-awaited GPT-5 model nears release and may be out by the time you read this.
With AI models increasingly used in AI agents, they are intelligent cogs in a larger system, providing reasoning, fact-grounding, and tool-calling to help the AI agent complete its task. AI model training and features have shifted to address Agentic AI needs.
Claude Opus 4.1 and OpenAI’s gpt-oss-120b and gpt-oss-20b open source models follow this trend, trained to be useful for agentic AI applications.
An Nvidia paper argues that Small Language Models (SLMs) are the future of agentic AI, due to performing well enough for typical AI agent requirements while being far more efficient.
OpenAI’s open AI models - gpt-oss-120b and gpt-oss-20b
OpenAI has made good on the ‘open AI’ name with their first open AI model releases since GPT-2. The open-weights AI models gpt-oss-120b and gpt-oss-20b are “permissively licensed” in Apache 2.0, so users can download and run these models locally, and customize or fine-tune the models.
The gpt-oss AI models are mixture-of-experts (MoE) models - gpt-oss-120b has 5.1B active parameters, and gpt-oss-20b has 3.6B active parameters - helping them deliver high performance very efficiently. The models support customized reasoning effort level.
Both gpt-oss-120b and gpt-oss-20b score very highly across coding, math and academic benchmarks. They saturate AIME 2025 with scores of 98%, get double digits on Humanity’s Last Exam, and are on par with o3-mini on Codeforces and other academic benchmarks.
However, early vibe-checks on the gpt-oss models show the releases appear to be “benchmaxxed.” They were trained mostly on synthetic data to avoid copyright and be great on STEM benchmarks, but are not-so-great in real-world general knowledge tasks. Some of the vibe-code feedback:
Qwen3-coder-480B beats gpt-oss-120B on coding, winning 58% of the time.
“gpt-oss-120b is incapable of producing linguistically correct German text.”
It also did poorly on general knowledge vibe tests, doing poorly on Korean.
One user got it to insert equations in poetry.
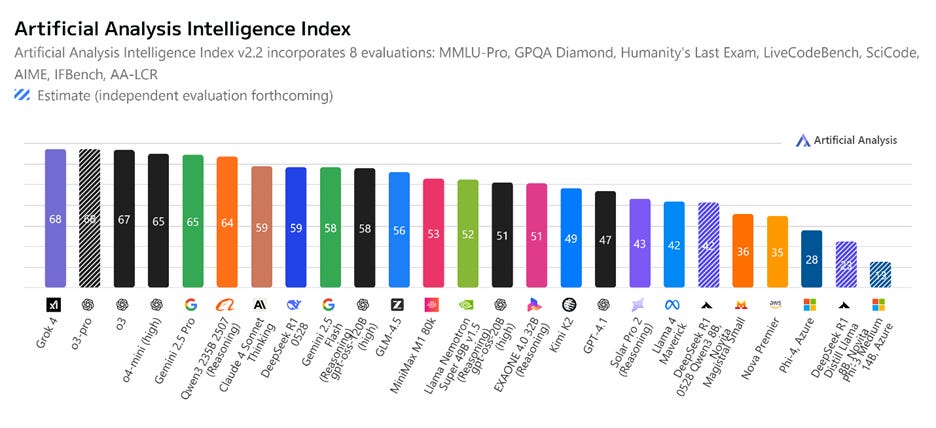
Evaluations from Artificial Analysis across a wider range of benchmarks put gpt-oss-120b on par with GLM-4.5 and Gemini 2.5 Flash, while putting gpt-oss-20B on par with models like EXAONE 32B, making them high-performing, even SOTA, models for their size.
OpenAI also reported strong evaluations on agentic AI; gpt-oss-120b get 67.8% and gpt-oss-20b gets 54.8% on Tau-Bench retail:
Both models also perform strongly on tool use, few-shot function calling, CoT reasoning (as seen in results on the Tau-Bench agentic evaluation suite) and HealthBench (even outperforming proprietary models like OpenAI o1 and GPT‑4o).
Claude Opus 4.1
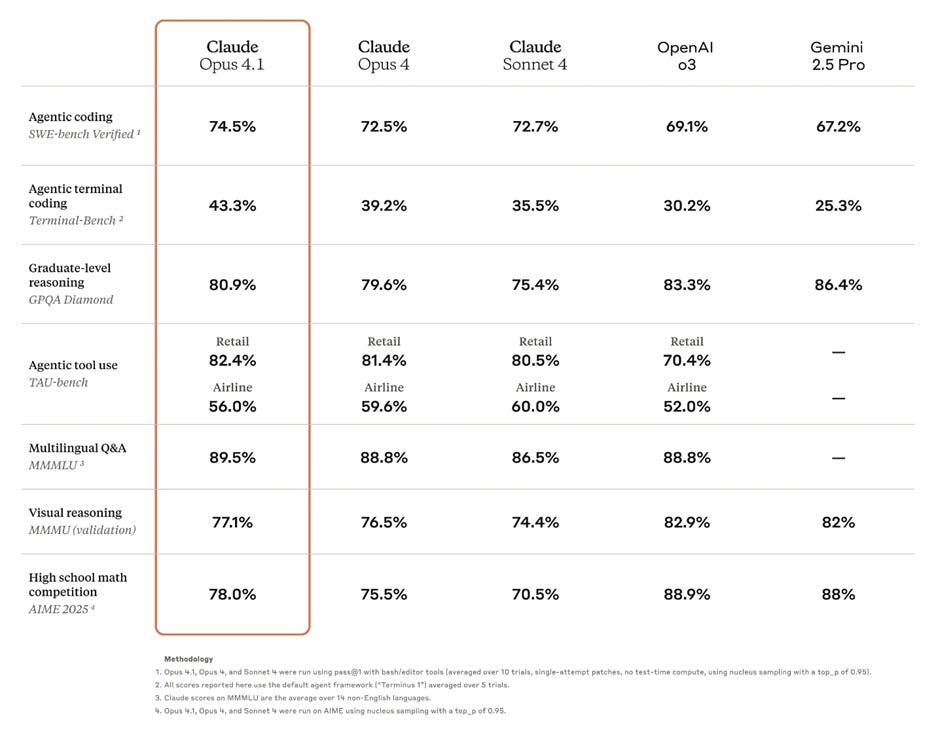
Anthropic released of Claude Opus 4.1, an incremental update to Claude 4, with the model getting slightly better across a range of metrics. The announcement was low-key and done to get out in front of the GPT-5 release.
The release announcement highlighted Claude’s performance on coding and agentic tasks, the sweet spot that makes Claude popular. Unless and until GPT-5 eclipses it, Claude Opus 4.1 is the highest-performing AI coding model in the world, with a SWE-bench verified score of 74.5%.
Small Language Models for Agentic AI
The paper Small Language Models are the Future of Agentic AI from Nvidia research makes the case that Small Language Models (SLMs) are all you need for human-level-performing agentic AI:
Small language models (SLMs) are sufficiently powerful, inherently more suitable, and necessarily more economical for many invocations in agentic systems and are therefore the future of agentic AI.
This paper suggests a common-sense path to building AI agents that are highly efficient, challenging the core assumption that you need the most advanced AI models to run useful agents.
A Small Language Model (SLM) was defined in the paper as an AI model under 10B parameters, small enough to run on your laptop or edge device. The SLMs used in the paper include Phi-3, Hymba, Nemotron-H, and R1-Distill-7B, among others.
SLMs have advantages due to their smaller size. They are cheaper and faster than larger AI models. SLMs can in some cases be run on edge devices, which provide added advantages: Privacy, ability to run off-line, and freedom from Big Tech infrastructure or subscriptions.
Open-source SLMs empower end-users further by supporting customization through fine-tuning. This can help SLMs perform as well in specific narrow domains as well as a larger model.
Most AI agents don’t need the power of GPT-5 and Claude 4 for all their tasks but instead use multiple invocations of an AI model to do narrow, repetitive tasks. The authors tested this across 3 real-world AI agents: MetaGPT, Open Operator, and Cradle. They found that 40% to 70% of tasks could be completed by SLMs without affecting AI agent performance.
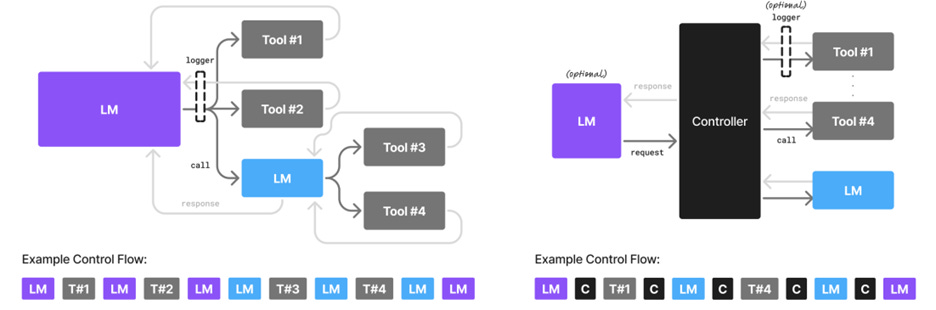
The counterargument might be that you still need a high-performance AI model to orchestrate responses. In those cases, the authors suggest that “heterogeneous agentic systems (i.e., agents invoking multiple different models) are the natural choice.” While the AI orchestration model is a frontier model, specialist SLMs suffice for sub-agent tasks, performing like tools in a toolbox.
The authors propose architecting AI agent systems for efficiency:
Utilize SLMs for Cost-Effective AI agents. AI agent builders should adopt SLMs in agentic applications to reduce latency and costs, particularly in scenarios where on-device inference is needed.
Design Modular Agentic Systems using a heterogeneous model approach. This means leveraging SLMs for routine, narrow tasks and reserving LLMs for more complex reasoning.
Leverage SLMs for Specialization. Teams should fine-tune SLMs for specific tasks, to further adapt them to evolving requirements.
Conclusion
As part of the platform shift to AI agents, the latest released AI models are increasingly trained and built for agentic AI applications. OpenAI’s gpt-oss models and Claude 4.1 Opus 4.1 follow this trend.
OpenAI’s gpt-oss-120b and gpt-oss-20b are highly efficient MoE models and the best American open-weights AI models now available. While the gpt-oss models benchmark well on STEM tasks, the ‘vibe checks’ shows their real-world performance drops off on general knowledge and multi-lingual tasks. However, for STEM-related tasks within an AI agent application (including coding tasks) these models may be more than sufficient.
The Nvidia paper makes the case that using SLMs in AI agents better balances performance, cost, and flexibility. For now, users place more value on the best result over cost-efficiency, and so they prefer the best frontier AI model, especially when working on the most challenging problems.
Claude 4 models are the most popular in AI coding assistants because they yield the best results. Users pay up for a higher token cost rather than use a much cheaper but not quite as good AI model for coding because the productivity efficiency gains are worth it.
Claude Opus 4.1 is keeping the Claude model on the frontier with incremental improvements across the board. Incrementally better than Claude Opus 4, it is the best AI coding model available and is trained to do well on agentic AI tasks.
This doesn’t undercut the case for SLMs in AI agents entirely. AI agents based solely on large costly AI models are overbuilt, and the latest SLMs that are built for agentic tasks can perform almost equally as well very efficiently.
Recently released small MoE models are both efficient and high-performance on agentic tasks. For example, gpt-oss-20b and qwen3-Coder-30b-3b have only 3B active parameters, yet Qwen3-coder-flash scores above 50% on SWE-bench verified in an agentic AI setting, while gpt-oss-20b claims Codeforces scores better than o3-mini.
The balance between performance and cost-efficiency can be met by heterogeneous AI agent designs that use a frontier AI model as the AI agent orchestrator and then use SLMs for sub-agent tasks. This puts a frontier AI model like Claude Opus 4.1 or GPT-5 in the role of orchestrator, calling on efficient SLMs like gpt-oss-20b and Qwen3-coder-flash to perform sub-tasks, treating them as tools in the AI agent flow.